Agentic AI & Autonomous Coding Systems in 2026: The New Engineering Workforce
Why engineering teams are moving from autocomplete copilots to autonomous multi-agent coding systems with self-healing pipelines in 2026.
Read article
Field service apps photo-diagnosing equipment, insurance claim photo + description analysis, warehouse pick verification, medical intake forms with document photos, and accessibility features combining voice plus screen context. If text-only RAG solves it, do not add vision complexity.
Separate perception from reasoning: vision model extracts structured facts (JSON), LLM reasons over facts plus user text. Keeps prompts smaller, costs lower, and debugging easier — you know whether the bug was 'saw wrong' vs. 'reasoned wrong'.
When rolling out changes related to Building Multimodal AI Apps, start with a two-week technical spike on the riskiest integration point. Document assumptions, measure baseline metrics, and define rollback before touching production traffic.
Decide who owns the cost model before you ship. Vision and audio tokens dwarf text, and a feature that looked cheap in testing behaves very differently once users start uploading whatever they like.
The recurring failure is treating each modality as an independent feature. Users expect a photo, a voice note, and a question about both to land in one conversation, and retrofitting that shared context is far harder than designing for it.
The costly mistake is building the demo before the input constraints. Decide what file sizes, formats, and durations you accept first, because those limits shape the pipeline more than the model choice does.
Our architects offer a free 30-minute consultation — no sales pitch, just answers.
Why engineering teams are moving from autocomplete copilots to autonomous multi-agent coding systems with self-healing pipelines in 2026.
Read article
Why rigid tables and static forms are dying, and how generative software renders intent-driven micro-interfaces in real time in 2026.
Read article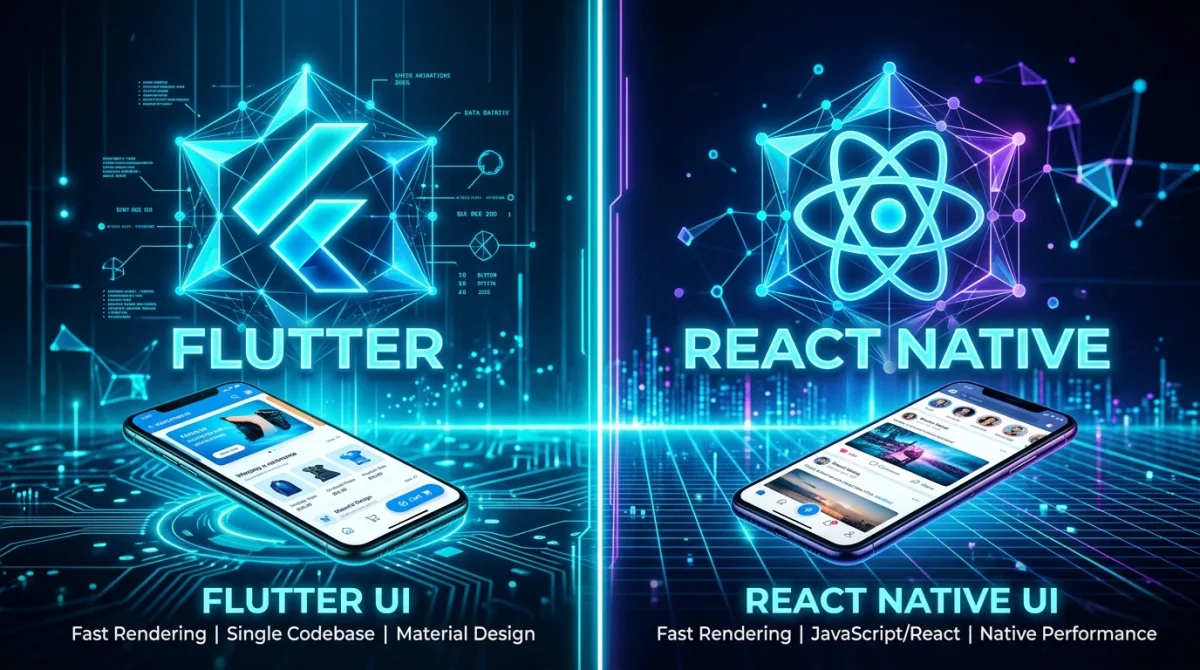
Flutter Impeller vs React Native Fabric benchmarked for 2026: frame rates, cold start times, memory use and AI bridging, with data from real builds.
Read article